

What is context engineering? A practical guide for LLM applications
Context engineering is the practice of controlling the information assembled for each model request, including retrieved documents, conversation history, memory, tool output, user data, and runtime metadata. Because those inputs change independently of the prompt, application quality can regress even when the instructions stay untouched. Effective context engineering depends on selecting relevant information, removing stale or conflicting content, structuring the payload clearly, and managing the available token budget before the model runs.
Braintrust makes context quality measurable across development and production by connecting assembled payloads to traces, scorers, experiments, and regression datasets. Production failures can become evaluation cases, and context changes can be compared against the same quality criteria before release. Start free with Braintrust.
What is context engineering?
Context engineering is the practice of designing and managing everything a language model receives for a single request. It covers how each context source is selected, ordered, compressed, and fitted within the context window.
Prompt engineering focuses on the instructions themselves, whereas context engineering governs the information assembled around those instructions at request time. Application code rebuilds the context for every request based on the user, query, retrieval results, stored memory, and current application state. When those inputs change, response quality changes with them, whether or not the prompt was edited.
The context window also imposes a fixed token budget across instructions, examples, history, retrieved evidence, and tool results. Redundant content consumes space needed for relevant evidence, so selection, ranking, deduplication, compression, and truncation become part of the application logic that determines what the model ultimately receives. Log and score the assembled payload. A regression then points to a specific assembly decision instead of a vague quality drop.
Context components in an LLM application
The context sent to a model comes from several sources, and each source can affect response quality differently.
System instructions define the model's role, constraints, output format, and refusal behavior. Although these instructions usually change less often than other context components, growing history, retrieved content, and tool output can reduce their influence within a long payload.
Few-shot examples demonstrate the expected reasoning pattern or response structure. Static examples can become less representative as the application evolves, while dynamically selected examples depend on their own retrieval and ranking logic.
Conversation history preserves information from earlier turns so the model can maintain continuity across a session. As a conversation grows, indiscriminate truncation can remove the earlier messages that established the task or important constraints.
Retrieved documents provide external evidence relevant to the current request. Retrieval determines which information becomes available to the model, while context assembly determines how much of that information is retained and where it appears in the final payload.
Memory and persisted user state carry information across sessions, including preferences, previous decisions, and account history. Stored records go stale when the underlying facts change, so validate freshness before a memory record enters a new request.
Tool definitions and results tell the model which actions are available and return information from external systems. Tool responses can vary widely in size and structure, so an unfiltered API response can take a disproportionate share of the available context window.
User and account data provide request-specific information such as entitlements, locale, plan details, and identity-related attributes the application needs. Context assembly must respect the application's permission boundaries so information unavailable to the current user does not enter the model request.
Application metadata provides runtime information such as the current time, request source, feature flags, and tenant configuration. Although metadata often occupies little space, omitting relevant runtime details can cause incorrect responses to questions that depend on the application's current state.
Context engineering vs. prompt engineering, RAG, memory, and fine-tuning
These practices are often discussed as alternatives, but most of them are inputs to context engineering rather than substitutes for it. The distinction that matters is what each one controls and when it changes.
| Practice | What it controls | When it changes | How it is measured |
|---|---|---|---|
| Context engineering | The complete payload assembled for each request: selection, ordering, freshness, compression, and token budget | Every request, as retrieval results, history, memory, and application state change | Context precision and recall, groundedness, utilization, token share, plus task outcome |
| Prompt engineering | The instructions, examples, and output format inside that payload | On deliberate edits, versioned like code | Score movement on a fixed dataset between prompt versions |
| RAG | How external documents are indexed, retrieved, and ranked into the candidate set | When the corpus, chunking, embeddings, or retrieval depth change | Retrieval metrics such as precision, recall, and NDCG@K |
| Memory | What persists across sessions, and how records are written, read, and expired | As user state accumulates and stored facts go stale | Record freshness, contradiction rate, and whether recalled records improve task outcomes |
| Fine-tuning | Behavior baked into the model weights themselves | On a training run, not at request time | Held-out evaluation against the base model |
RAG and memory supply candidates that context engineering then selects from, so improving either one does not guarantee a better payload. Fine-tuning is the only practice in this list that changes the model rather than its input, which makes it the slowest lever to adjust when quality drops.
Also read:
Core context engineering techniques
Context selection and relevance filtering
Context selection determines which candidates from retrieval, memory, and tool output actually enter the model request. A fixed top-K cutoff treats retrieval rank as a proxy for usefulness, which can include unnecessary material for narrow questions and exclude useful evidence for broader ones. Relevance thresholds, reranking, and minimum-score filters make the amount of included context responsive to the request instead of forcing every query into the same document count.
Context ordering and position within the window
Information does not receive equal attention across a long context window, so placement affects how reliably the model uses what it receives. Instructions and constraints need prominent positions, retrieved evidence should follow a deliberate relevance order, and the current request should remain close to the generation boundary. Reordering the same material can improve response quality without increasing token usage or retrieval volume.
Context formatting and structure
Formatting helps the model distinguish instructions from evidence, history, metadata, and tool output. Consistent section boundaries, field names, and source labels let the model attribute claims to the source that supplied them. A structured payload lets you score history, evidence, and tool output as separate components.
Context compression and summarization
Compression creates room in the context window by reducing information that does not need to remain in full. Conversation history can be summarized, long documents can be narrowed to relevant passages, and verbose tool responses can be reduced to the fields required for the task. Because each compression step can remove information needed later, regression tests should cover changes to summarization or filtering policies.
Deduplication and contradiction resolution
Duplicate documents, overlapping chunks, and repeated memory records consume tokens without adding new evidence, so deduplicate before final assembly. Contradictory sources require a separate decision based on criteria such as recency, source authority, or explicit precedence rules. When the application cannot resolve a conflict reliably, keep both sources in the payload with explicit labels showing their date and origin.
Context freshness and invalidation
Retrieved documents, memory records, and cached tool results can all become outdated at different rates. Freshness policies attach timestamps or expiry rules to each source and either refresh or exclude information that has exceeded its allowed age. Carrying timestamps into the model payload can also help the model distinguish current evidence from older material when both remain relevant.
Context window budgeting and token allocation
Token budgeting reserves space for each part of the request before final assembly. A defined allocation can protect instructions, cap conversation history and tool output, and leave the remaining capacity for retrieved evidence. The overflow policy matters because uncontrolled truncation can remove whichever component appears last, causing a quality regression without producing an application error.
The context assembly workflow at runtime
Context assembly is the request-time pipeline that turns candidate information into the exact payload sent to the model. Filtering, conflict resolution, compression, ordering, and truncation can each change what survives into generation, so each stage should log what it dropped and why.
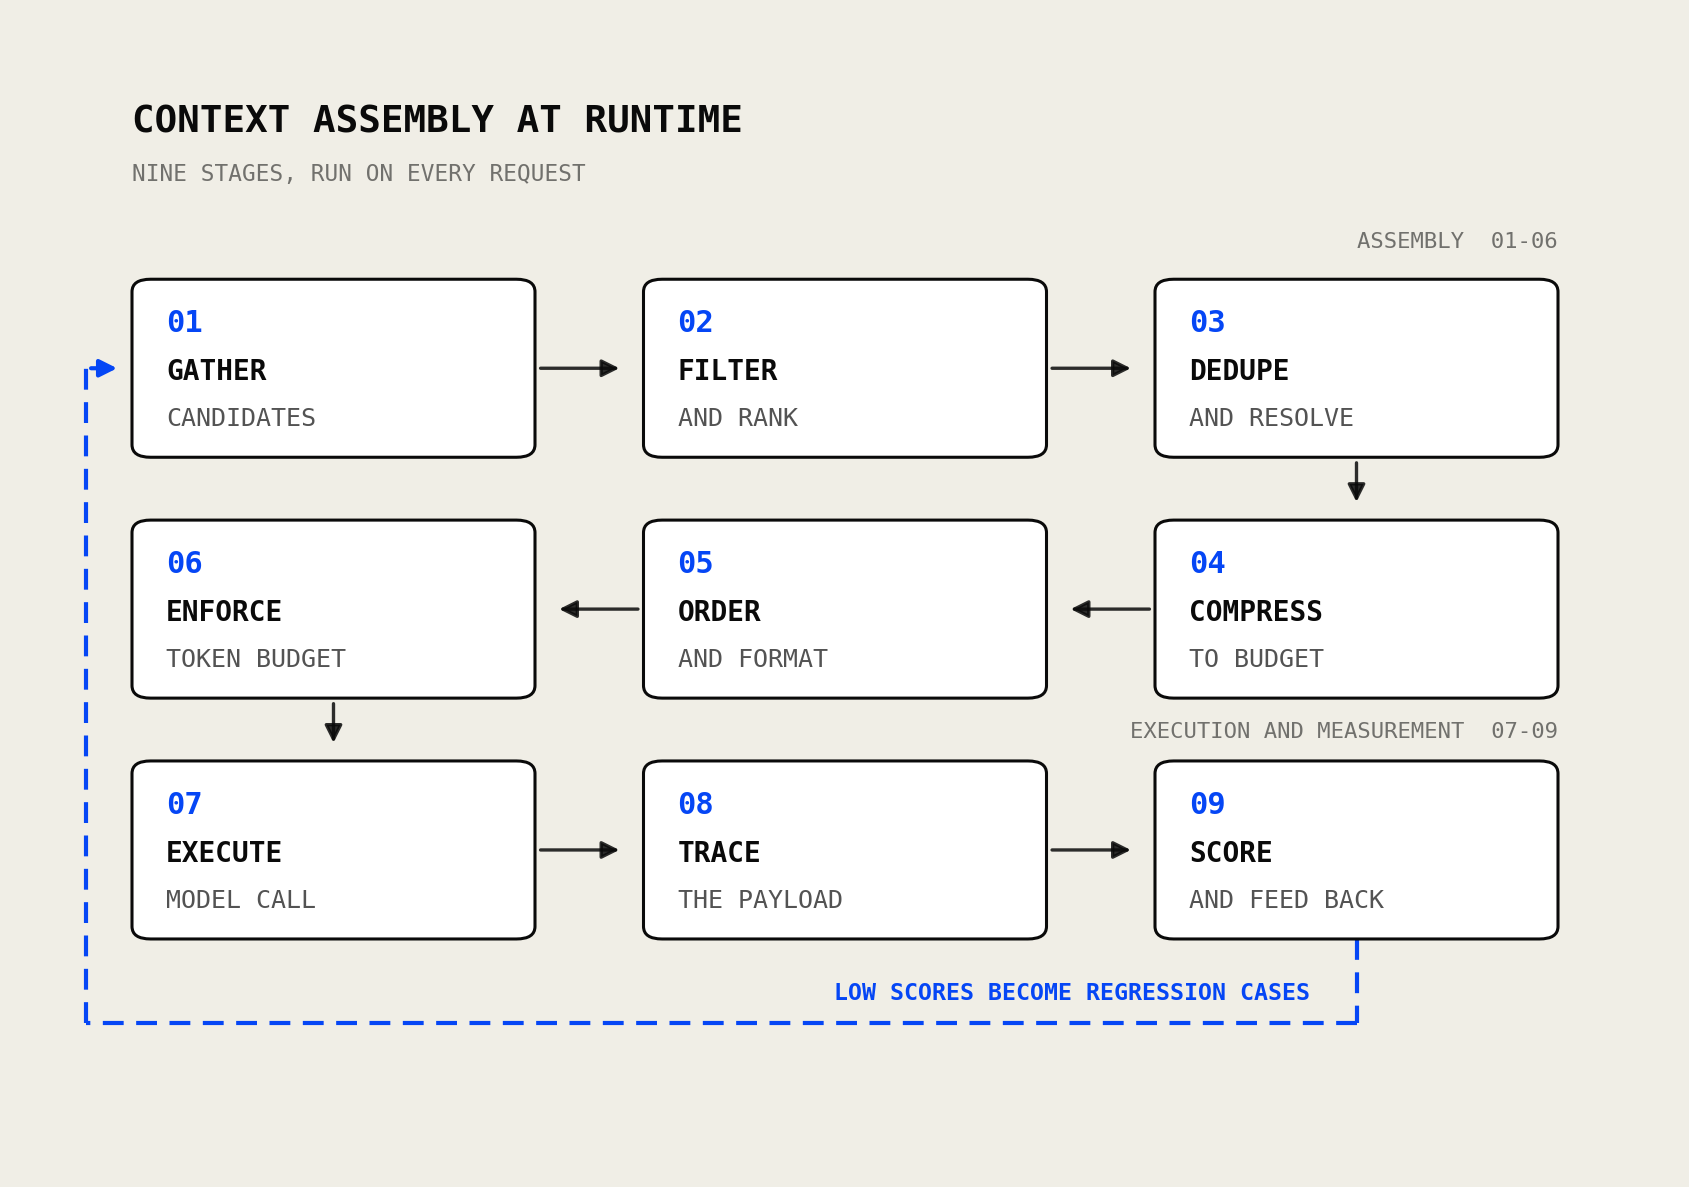
Stages one through six build the payload, while seven through nine execute it and feed low scores back as regression cases.
1. Gather candidate context: Collect potentially relevant material from retrieval, memory, tool calls, and application state before applying the final token budget. Broad collection at this stage reduces the chance that useful evidence is excluded before assessing relevance.
2. Filter and rank candidates: Score the collected material against the current request, remove items below the relevance threshold, and rerank the remaining candidates.
3. Deduplicate and resolve conflicts: Collapse overlapping or repeated sources, then apply explicit precedence rules when two candidates disagree. Recency, source authority, or application-defined priority can determine which version is retained.
4. Compress against the budget: Reduce conversation history, long documents, and verbose tool responses without removing information required by the task. Evaluate compression policies independently, because a shorter payload can still fail if summarization removes a critical detail.
5. Order and format the payload: Arrange instructions, evidence, history, metadata, and the current request in a deliberate sequence with consistent labels and boundaries. Clear structure helps the model distinguish instructions from supporting information and makes individual context components easier to inspect later.
6. Enforce the token budget: Measure the assembled payload against the target model's context limit before execution. If the request exceeds the limit, apply a defined truncation order that removes the lowest-value material first and records exactly what was dropped.
7. Execute the model call: Send the final payload to the model and capture the response together with token usage, latency, and other request metadata needed for evaluation.
8. Trace the assembled context: Record the selected sources, their order, age, token share, and any filtering or truncation decisions in a structured trace. Advanced tracing in Braintrust keeps each stage inspectable, which makes it possible to connect a low score to the context that actually reached the model.
9. Score and feed results back: Evaluate both the assembled context and the final response, then move failed or low-scoring production cases into regression datasets. Those cases provide concrete coverage for the next change to retrieval, memory, compression, or assembly logic.
How to evaluate context quality
Evaluating only the final response makes it difficult to tell whether a failure originated in retrieval, context assembly, or model behavior. Scoring the assembled payload alongside the output makes those failure sources easier to separate and provides a consistent way to compare changes to selection, ordering, compression, and token allocation.
Retrieval metrics for context selection
Retrieval metrics measure whether the right evidence entered the candidate set before assembly. Context precision shows how much of the included material is relevant, context recall measures how much relevant information was captured, and ranking metrics such as NDCG@K show whether the strongest evidence appeared near the top. These metrics isolate selection quality from problems introduced later by ordering, compression, or truncation.
Groundedness and context utilization scoring
Groundedness measures whether claims in the response are supported by information supplied in the context, while context utilization measures how much of that supplied information actually contributed to the response. A payload may contain eight relevant documents but consistently draw from only the first two, revealing unnecessary token use or an ordering problem even when retrieval precision remains high.
Task success and end-to-end outcome metrics
Strong component scores do not guarantee that the application completed the user's task correctly. End-to-end evaluation measures the final outcome through criteria such as reference-based correctness, rubric-based judging, or application signals such as resolution without escalation. Braintrust evaluations support combining these outcome measures with context-level scorers so improvements to assembly logic are judged by their effect on application quality.
Ablation testing for context components
Ablation testing measures the value of individual context decisions by changing one variable and rerunning the same evaluation dataset. An experiment might remove memory, reduce retrieved documents from eight to four, reverse evidence order, or replace summarized history with the original transcript. Comparing the resulting scores shows whether a component contributes enough value to justify its token cost and complexity.
Regression datasets and CI gates
Any change to retrieval depth, chunking, memory fields, or compression policy changes the assembled payload. Production cases that previously exposed context failures belong in a persistent regression dataset, with the evaluation rerun whenever assembly logic changes. Defined score thresholds can then prevent changes that reintroduce known failures from progressing through the release process.
Online scoring for production context
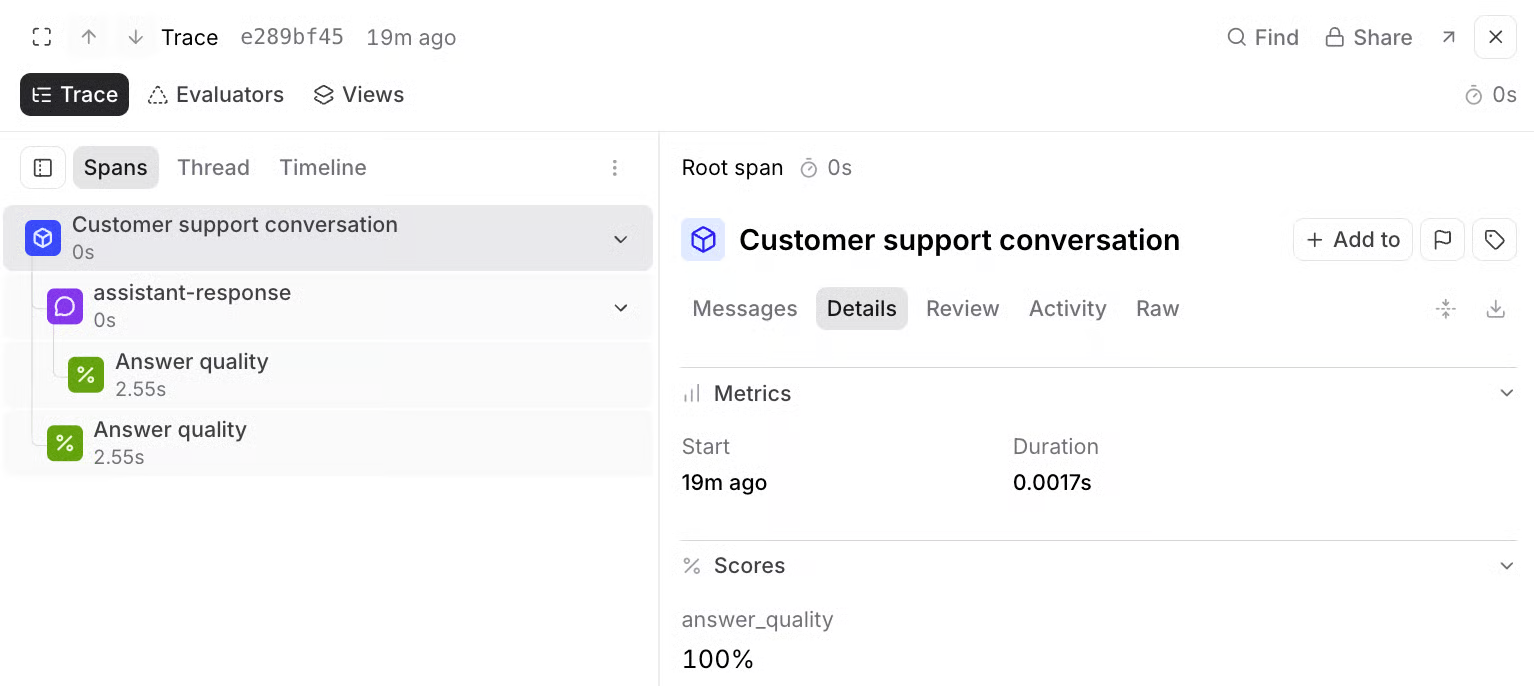
Online scoring records each scorer run as a span inside the production trace, so context scores sit next to the request that produced them.
Offline datasets cannot represent every context combination encountered in live traffic. Online scoring applies context scorers to sampled production traces, making gradual changes such as corpus drift, memory accumulation, and growing conversation history visible over time. Low-scoring production traces can then become new regression cases, extending offline coverage with conditions observed in real usage.
Common context engineering failures and how to detect them
Most context failures produce a plausible response rather than an error, which is why each one needs a specific detection signal rather than a general quality check.
| Failure | What it looks like | How to detect it |
|---|---|---|
| Missing evidence | A confident answer with no supporting source in the payload | Low context recall, plus a groundedness scorer flagging unsupported claims |
| Relevant evidence ignored | The right document is present but the answer does not use it | High context precision paired with low utilization; ablation on evidence order |
| Silent truncation | Quality drops with no application error, usually losing whichever component lands last | Log the truncation decision per request and alert on truncation frequency |
| Stale memory or documents | The answer reflects a fact that has since changed | Carry timestamps into the payload and score record age against a freshness policy |
| Contradictory sources | Answers flip between runs on the same query | A contradiction scorer across sources, with repeated trials to expose the variance |
| Context bloat | Token usage and cost rise while quality scores stay flat | Token share per source in the trace, plus ablation to find components that do not earn their space |
| History crowding out evidence | Later conversation turns degrade while early turns were fine | Per-component token budgets tracked against conversation length |
| Permission leakage | Content outside the requester's scope enters the payload | A deterministic scorer asserting every included source is within the current user's permissions |
Also read:
- Detecting prompt injections for a practical Braintrust evaluation example
- Best LLM guardrails and security testing tools for broader coverage of prompt injection, guardrails, and security testing
How to implement context engineering with Braintrust
A reliable context workflow needs traces that record the assembled payload, datasets that preserve production failures as regression cases, and release checks that show whether changes improve or degrade quality. Braintrust connects tracing, datasets, scorers, experiments, CI evaluations, and production monitoring so you can evaluate context assembly before release and track it after deployment.
Step 1. Log the assembled context as a structured span
Instrument context assembly as its own span so the exact payload remains inspectable after the request completes. Record the selected sources, their order, age, token share, and other assembly metadata needed to explain why a particular response succeeded or failed.
import braintrust

with braintrust.start_span(name="Retrieve documents") as span:
    docs = retrieve_documents()
    span.log(output={"count": len(docs)})
Extend span.log with the fields you need to explain a failure later: source IDs, their order in the payload, record age, and token share per source. Separate spans for retrieval, memory lookup, compression, and final assembly show which stage changed when groundedness drops.
Step 2. Curate datasets from production traces
Synthetic test cases rarely capture the full range of production context conditions, such as long conversation histories, accumulated memory, or queries that retrieve content close to expiry. Braintrust datasets preserve representative production cases as versioned evaluation inputs, so future assembly changes can test against the same cases.
import braintrust

dataset = braintrust.init_dataset(
    project="Support bot",
    name="Golden questions",
)

dataset.insert(
    input={"question": "How do I reset my password?"},
    expected={"answer": "Use the account recovery flow."},
    metadata={"source": "docs"},
)

dataset.flush()
Loop, Braintrust's natural-language query layer over production logs, reduces the engineering work required to find useful cases. A request such as finding traces where the context approached the token limit can surface candidates for a regression dataset without requiring hand-written log filters.
Step 3. Define scorers for context quality
Start with a deterministic scorer to establish a baseline.
import braintrust
from pydantic import BaseModel

project = braintrust.projects.create(name="Support bot")


class EqualityInput(BaseModel):
    output: str
    expected: str


def equality_scorer(output: str, expected: str):
    return {"score": 1 if output == expected else 0}


project.scorers.create(
    name="Equality scorer",
    slug="equality-scorer",
    handler=equality_scorer,
    parameters=EqualityInput,
)
Calling create() only registers the scorer in your file; bt functions push bundles and uploads it. The same project.scorers.create pattern registers code-based checks on token allocation, required instructions, or maximum record age, as well as LLM-as-a-judge scorers for groundedness, utilization, and cross-source contradictions.
Step 4. Run ablation experiments across assembly variants
Run each context variant against the same dataset and scorers so the effect of one assembly decision remains measurable. Useful comparisons include changing document count, evidence order, compression policy, or memory inclusion without altering several variables at once.
from braintrust import Eval

Eval(
    "Support bot",
    data=lambda: [
        {
            "input": "How do I reset my password?",
            "expected": "Use the account recovery flow.",
        }
    ],
    task=lambda input: answer_question(input),
    scores=[equality_scorer],  # the scorer registered in Step 3
)
Experiment results expose both aggregate score changes and case-level regressions, so an improvement in the average cannot hide a failure on an important query type. The Braintrust Playground supports the same comparison interactively when engineers and product teams need to test variants against production examples.
Step 5. Gate context changes in CI
Context assembly changes often arrive through ordinary pull requests, including updates to chunking, retrieval depth, memory fields, or compression logic. The Braintrust GitHub Action runs evaluations during review and reports improvements and regressions against the baseline experiment on the pull request. Reporting on its own does not block anything. By default bt eval exits non-zero only when an eval throws an exception, and scorer pass thresholds only mark individual results as passing or failing. Turning a low score into a failed check requires a custom Reporter() whose report_run returns false when results fall below your release criteria, since that return value is what sets the process exit code the action reports on.
Step 6. Monitor context quality in production
Offline evaluations protect known cases, but production monitoring is needed for changes that emerge gradually as real traffic evolves. Braintrust dashboards can track signals such as groundedness, context precision, token usage against the model limit, truncation frequency, and cost per request, with alerts configured around meaningful thresholds.
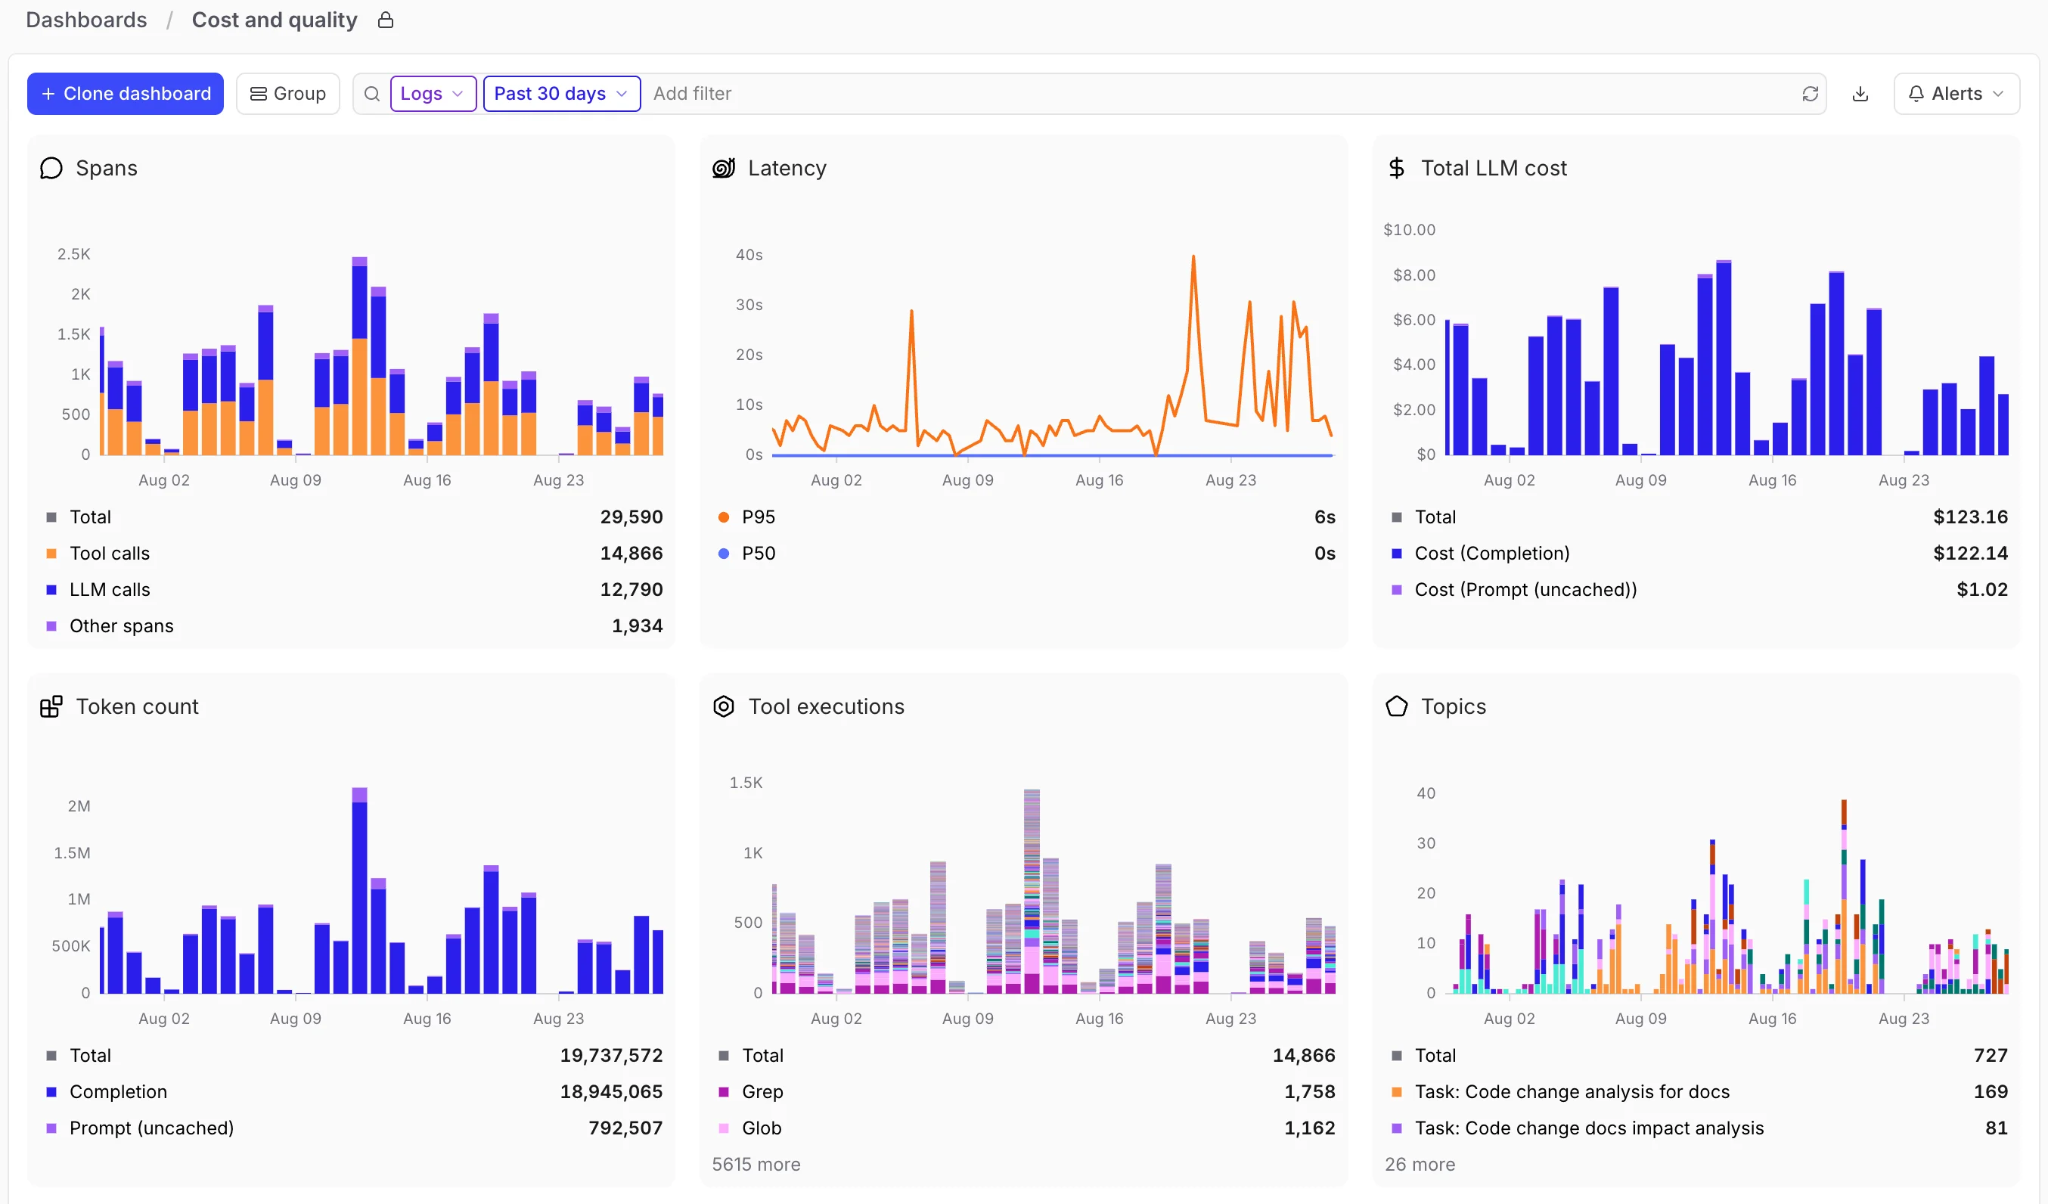
A dashboard puts token count and cost next to latency and quality, which is where context bloat becomes visible before it shows up as a score drop.
Low-scoring production cases can be added to regression datasets and tested against future context changes. Notion, Stripe, Zapier, Vercel, Airtable, and Ramp run their evaluation workflows on Braintrust, connecting production failures with the offline tests used to prevent the same behavior from returning.
Evaluate context changes before they reach production with Braintrust →
FAQs about context engineering (2026)
What is context engineering?
Context engineering is the process of deciding what information a model receives for each request and how to prepare it before generation. The scope includes retrieved documents, conversation history, memory, tool results, user data, and runtime metadata, along with decisions about relevance, ordering, freshness, compression, and token allocation. The goal is to give the model the information required for the task without letting outdated, conflicting, or unnecessary content weaken the response.
How is context engineering different from prompt engineering?
Prompt engineering improves the instructions that tell a model what to do, while context engineering controls the information available when the model carries out those instructions. Prompt wording usually changes through deliberate edits, but context changes from request to request as retrieval results, conversation history, memory, and application state change. A strong prompt can therefore produce poor results when the information surrounding it is incomplete, stale, or poorly assembled.
How do I evaluate context quality?
Measure context quality before and after generation. Selection metrics show whether the request contains relevant evidence, groundedness measures whether the response is supported by that evidence, and utilization scoring reveals whether the model actually used useful context. Task-level scores then confirm whether the complete request produced the required outcome. Braintrust scorers can combine deterministic checks with LLM-as-a-judge criteria, making context properties and response quality measurable in the same evaluation.
How can I make sure my RAG pipeline is returning the right results?
Evaluate retrieval independently from the final answer first. Context precision and recall show whether the pipeline returned relevant documents, while ranking metrics such as NDCG@K reveal whether the strongest evidence appeared high enough in the results. Good retrieval scores are not sufficient on their own because relevant documents can still be removed, compressed too aggressively, or lose space to conversation history during context assembly.
How do I measure whether changes to my RAG system improve accuracy before shipping?
Run the current and proposed configurations against the same evaluation dataset and score both versions using identical criteria. Compare overall score changes alongside individual cases, since a higher average can still hide regressions on important queries. Braintrust experiment comparisons provide the case-level and aggregate results needed to decide whether changes to retrieval, chunking, reranking, or context assembly meet the existing release requirements.
How much context should I include in a single request?
Include enough context to support the task, then measure whether adding more information continues to improve the result. Testing different retrieval depths, history lengths, and memory allocations against the same evaluation cases reveals when additional context stops improving accuracy and starts increasing noise, latency, or token usage. Because a narrow factual question and a broad synthesis task require different amounts of evidence, context limits usually work better when they respond to the request instead of relying on one fixed top-K value.